allnewscastallnewscast
Breaking News
AI & Tech

OpenAI Says AI’s Next Economic Test Is Turning Big Ideas Into Finished Work
Nic Reeve5 min read
OpenAI Says AI’s Next Economic Test Is Turning Big Ideas Into Finished Work

OpenAI published “The eternal complement” on October 1, 2026, an essay arguing that advanced artificial intelligence may create its greatest economic value through the routine work required to turn ambitious ideas into functioning systems. The discussion adds a new angle to AI news by focusing less on machine-generated breakthroughs and more on execution, coordination and institutional capacity.

What did OpenAI publish?

OpenAI released the essay through its Intelligence Age platform on October 1, 2026. The article was written by Hemanth Asirvatham and Elliott Mokski, who present a framework for understanding how frontier intelligence interacts with the organizations and systems needed to apply it.

The publication is an essay, not a product announcement, model launch or performance benchmark. OpenAI’s newsroom lists “The eternal complement” as part of its Intelligence Age material, while Unite.AI describes it as the first entry in a planned series about the next economy.

  • Publication date: October 1, 2026, according to OpenAI’s Intelligence Age index.
  • Authors: Hemanth Asirvatham and Elliott Mokski, according to Unite.AI.
  • Format: An analytical essay rather than a software or hardware release, according to OpenAI’s newsroom listing and reporting by Remio.ai.

What does “eternal complement” mean?

The essay uses the economic idea of complements, or inputs whose value rises when they are used together. Asirvatham and Mokski apply that concept to advanced machine intelligence and the practical ability to carry ideas through development, regulation, funding and production.

According to Unite.AI’s October 1 report, the authors call this often-overlooked execution capacity “institutional intelligence.” The term covers the laws, bureaucratic processes, financing arrangements, supply chains and specialist coordination that stand between a promising concept and a usable result.

The central argument is direct: smarter systems do not remove the need for execution. They can increase the value of people and institutions capable of carrying out difficult, repetitive or highly coordinated work.

Why does the essay focus on routine work?

The publication argues that advanced systems may matter most when they reduce the cost of work that is necessary but rarely celebrated. The essay points to activities such as writing code, searching unfamiliar research and converting rough concepts into working prototypes, according to Unite.AI.

Remio.ai’s October 2 analysis characterizes the argument as a shift from asking whether AI can generate an answer to asking whether the answer can become a completed project. That process can require repeated testing, documentation, approvals, hiring, procurement and technical integration.

Routine does not mean unimportant. A discovery that cannot be tested, financed or deployed has limited practical effect.

  • Research: Systems can help locate and interpret unfamiliar literature, according to Unite.AI.
  • Software: AI can assist with code and early prototypes, according to Unite.AI.
  • Implementation: Organizations still need to manage rules, resources, specialists and supply chains, according to the essay’s description in Unite.AI and Remio.ai.

Is OpenAI announcing a new product?

No. The October 1 publication does not announce a model, subscription, API, benchmark or commercial deployment. OpenAI’s newsroom places the piece in the Intelligence Age section, and Remio.ai explicitly describes it as a framework for judging how advanced systems might translate ideas into broader material progress.

That distinction matters for readers following the company’s product releases. The essay sets out a view about economics and organizational change. It does not provide a new capability that customers can download or test.

OpenAI’s presentation also says the piece reflects the authors’ perspective rather than serving as a formal product specification, according to MediaRelease.co’s report on the publication.

What could change for workers and organizations?

The argument places execution-heavy occupations at the center of the next phase of automation. Workers who translate goals into code, reports, prototypes, compliance documents or operating procedures could gain tools that shorten the path from instruction to completed task.

That does not mean every role disappears. The framework instead suggests that the balance of work may change. People could spend less time producing first drafts and more time setting objectives, checking outputs, making judgments and handling exceptions.

Organizations face a parallel challenge. Faster generation can expose bottlenecks in approval systems, budgets, data access and procurement. A company may possess powerful software and still move slowly if its internal processes cannot absorb the output.

  • Potential beneficiaries: Small teams that can use machine assistance to perform work once requiring larger departments, according to Unite.AI.
  • Potential pressure points: Compliance, management, infrastructure and supply-chain functions that determine whether an idea reaches deployment, according to the essay’s framework.
  • Human responsibility: Goal-setting, verification and decisions involving risk remain central to the model described by the authors.

How does the publication fit OpenAI’s wider agenda?

OpenAI launched its Intelligence Age platform in August 2026, according to Unite.AI, presenting it as a venue for perspectives on advanced AI and the next economy. “The eternal complement” is listed as the platform’s first essay in the series.

The timing places the article within a wider debate about what increasingly capable systems will change beyond chat interfaces and software demonstrations. Rather than measuring progress only through benchmark scores, the essay asks whether institutions can convert technical ability into discoveries, products and public services.

That question extends beyond OpenAI. Governments, universities, companies and investors all control parts of the execution chain described in the essay. Their rules and capacity will influence how quickly machine-assisted ideas become real-world outcomes.

What happens next?

The immediate next step is further discussion through the Intelligence Age series. No launch date, business target or measurable forecast accompanied the October 1 essay, so its claims remain a strategic argument rather than a tested prediction.

Readers will likely judge the thesis against practical evidence: whether smaller teams can complete more complex projects, whether approval systems adapt to faster technical work and whether organizations invest in the less visible infrastructure needed for deployment.

The essay’s test is practical. Can intelligence survive contact with institutions?
Sources

  1. 1.syncai.news
  2. 2.openai.com
  3. 3.unite.ai
  4. 4.unite.ai
  5. 5.mediarelease.co
  6. 6.theaiwoods.com
  7. 7.erudite.news
  8. 8.unite.ai
  9. 9.news.tunx.ai
  10. 10.ethics.ai
  11. 11.laojinchuhai.com
  12. 12.remio.ai
  13. 13.syncai.news
  14. 14.openai.com
  15. 15.unite.ai

Read more →

Related Articles

Harvard Adds AI Avatars to a $699 Founder Bootcamp
AI & Tech

Harvard Adds AI Avatars to a $699 Founder Bootcamp

Harvard Business School has put an artificial-intelligence twist on entrepreneurship training, rolling out a new eight-week startup bootcamp that pairs live instruction with AI-generated instructor avatars. The program, known as HBS Foundry, costs $699 and is designed to give aspiring founders more personalized feedback during pitch practice and simulated board meetings. According to reporting from TechCrunch, the course uses avatars built by AI video platform HeyGen to mimic instructors and respond during exercises such as practice pitches and boardroom scenarios. The weekly live sessions are still led by real teachers, but the AI avatars are intended to extend the feedback students receive between those classes. The idea reflects a broader push by business schools and online learning platforms to make startup education more scalable without losing the feel of individualized coaching. In this case, Harvard is trying to blend human-led teaching with digital replicas that can deliver critiques in a format similar to a live conversation. The bootcamp is part of Harvard Business School’s effort to reach founders beyond its traditional degree programs. HBS Foundry is aimed at entrepreneurs who want practical guidance on shaping and testing ideas, refining their pitches and preparing for investor-style questioning. By using AI avatars, the program attempts to offer more frequent and accessible feedback than a standard classroom model might allow. CryptoRank’s coverage highlighted the novelty of the setup, and the story quickly spread across tech and startup media because of the contrast between Harvard’s elite brand and the mass-market feel of a $699 online bootcamp. The price point is notably lower than the cost of many executive education offerings, which makes the course more accessible to early-stage founders and operators. The use of AI avatars also raises questions that are now common across education and corporate training: how well can synthetic instructors capture the nuance of a seasoned mentor, and where is the line between useful automation and imitation? In this program, the avatars are not replacing live faculty altogether, but they are taking on a role that traditionally depends on one-on-one human interaction. HeyGen, the company behind the avatars, has been positioning itself as a tool for AI-powered video creation and presentation workflows. In Harvard’s bootcamp, its technology is being used for a more specific purpose: simulating instructor feedback in a startup-training environment. That makes the course one of the more visible examples so far of generative AI moving from demo use cases into formal education. The broader significance lies in what Harvard is signaling about the future of teaching entrepreneurship. If AI avatars can reliably provide structured feedback on pitches, board meetings and founder communication, similar systems could be adopted by other schools, accelerators and corporate training programs. If they fall short, the experiment will still serve as a useful test of how far AI can go in roles that depend on judgment, tone and mentorship. For now, HBS Foundry stands out less as a replacement for professors than as a hybrid model that uses software to extend their reach. That combination of live instruction and AI-driven personalization is likely to draw attention from founders looking for practical training — and from educators watching how far the technology can be pushed.

Nic Reeve·
Mistral’s Agentic Search Aims to Redefine Enterprise AI Retrieval
AI & Tech

Mistral’s Agentic Search Aims to Redefine Enterprise AI Retrieval

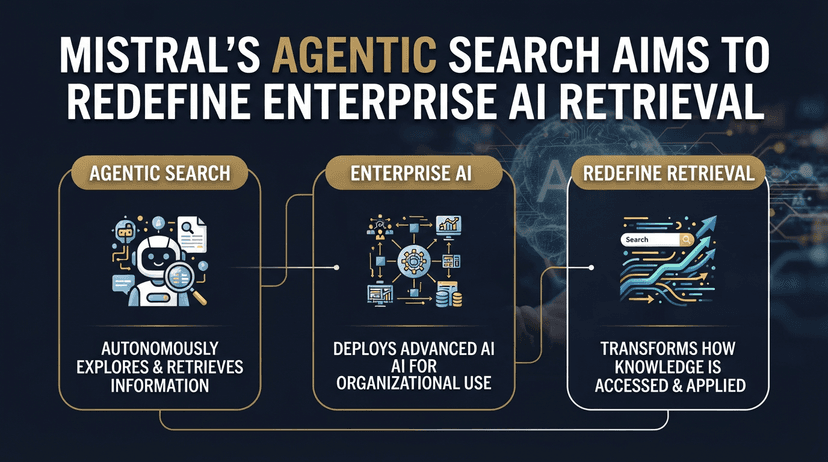
A New Retrieval Layer for Enterprise-Grade AI Mistral AI has introduced Agentic Search , a new retrieval layer designed to make AI systems markedly more accurate and efficient when working over complex enterprise data. The feature sits between large language models (LLMs) and an organization’s existing indexes, allowing models to actively search, open, navigate and verify information inside lengthy and heterogeneous documents rather than relying on a single retrieval pass. Unlike conventional retrieval‑augmented generation (RAG), which typically performs one vector or keyword lookup and feeds the top chunks into a model, Agentic Search orchestrates a multi‑step search loop . The model can iteratively refine queries, inspect multiple sources, and gather corroborating evidence before producing an answer, a workflow aimed squarely at the hard cases of enterprise question answering across filings, contracts, scanned PDFs and other long‑form content. How Agentic Search Works At the core of Mistral’s approach is a set of file‑style tools that the model can call autonomously during a session. Public documentation describes five primary capabilities exposed to the model: search – find relevant documents across an existing index or corpus. open – select and open a specific document returned by search. navigate – move to a particular page, section or region within the open document. read – retrieve the content at the current location for inspection. grep – search within the open document for exact strings or patterns. Together, these tools enable a model to behave more like an analyst than a passive text generator. When the first retrieved chunk does not contain the answer, the model can issue a new search, open a more promising file, jump to likely sections based on headings or page numbers, and then scan for precise terminology using in‑document search, all before finalizing its response. Already‑inspected chunks can be excluded, reducing redundancy and cost. This approach is especially important for questions that require cross‑document reasoning or precise citation of clauses buried deep within long documents. Instead of hoping that chunking and ranking surface the right passages on the first attempt, Agentic Search allows the model to keep looking until it has collected enough evidence. Benchmark Results: From One‑Shot RAG to Iterative Evidence Gathering Mistral is positioning Agentic Search as a measurable improvement over traditional RAG pipelines, backing the launch with benchmark data on datasets such as FinanceBench and OfficeQA Pro . According to the company’s published figures, running the full agentic loop – including both iterative search and document navigation – drove a dramatic jump in accuracy on FinanceBench compared with single‑shot RAG. Public reports summarizing Mistral’s results highlight accuracy gains from roughly the high‑20% range to the mid‑80% range for certain models when moving from one‑shot retrieval to Agentic Search. Iterative search alone contributed the majority of the improvement, with navigation and in‑document tools accounting for several additional percentage points. In other words, allowing the model to keep searching and then move intelligently within documents can more than triple its ability to answer complex financial questions correctly. The company also reports significant efficiency gains . By avoiding repeated retrieval of the same or irrelevant chunks and focusing only on promising portions of documents, Agentic Search reduces token usage and latency compared with a naive search‑only loop. Mistral’s internal tests indicate reductions in token consumption of around a quarter to a third for evaluated models, alongside double‑digit percentage cuts in tail latency on FinanceBench queries. On the OfficeQA Pro benchmark, which targets questions about office productivity and business documents, the multi‑step navigation stack similarly lowered token usage and improved responsiveness. These metrics are critical for enterprises deploying AI at scale, where every marginal improvement in latency and token cost can translate into substantial infrastructure savings. Built Into Mistral’s Search Toolkit, Studio and Vibe Agentic Search is being shipped as part of the broader Mistral Search Toolkit , a composable framework for building production‑grade search pipelines for AI applications. The toolkit is designed to run in diverse environments, from public cloud to on‑premises infrastructure, giving organizations flexibility over where their data and compute reside. For developers, Agentic Search is exposed through an SDK that can be integrated into custom agents, workflows and end‑user applications. The company emphasizes that it wraps around existing indexes rather than requiring new fine‑tuning of models or wholesale changes to data infrastructure. Teams can plug the agentic layer into their current search stack and let it handle the multi‑turn retrieval logic. For users of Mistral’s own products, the feature comes pre‑integrated into the Libraries capability within both the Studio interface and the Vibe agent. That means customers who store their knowledge bases in Libraries can benefit from the multi‑step retrieval loop without writing any additional code; the system automatically allows the model to search, open, navigate and read within the indexed content as it answers questions or executes tasks. Agentic Search also aligns with Mistral’s broader strategy around agentic AI. The company has previously rolled out an Agents API with web search connectors and continues to expand tools like Vibe for long‑horizon coding and research tasks. In this context, Agentic Search marks a focused push into enterprise knowledge search , complementing those agent capabilities with deeper document‑level understanding. Target Use Cases: From Filings to Contracts Mistral is explicitly targeting organizations with large, complex and often messy corpora. Typical examples include regulatory filings, annual reports, internal policy manuals, technical documentation, legal contracts and scanned PDFs produced by legacy workflows. These documents tend to be long, inconsistently formatted, and heavy on domain‑specific language – a challenging environment for standard chunk‑based RAG. In these scenarios, a user might ask, for example, about how a particular risk is disclosed across several years of a company’s filings, or which clause in a contract governs a specific edge case. Agentic Search allows the model to conduct a multi‑hop investigation: search across the corpus, open the most relevant documents, jump to sections that mention the relevant risk or clause, and cross‑check multiple sources before responding with a grounded, cited answer. Industry observers note that the approach is distinct from consumer‑oriented web search. Rather than crawling the open internet, Agentic Search is focused on private, high‑value enterprise data where precision and verifiability are more important than breadth. The trade‑off is that the agentic loop can take longer – sometimes running for minutes on especially hard questions – but the resulting accuracy and auditability are intended to justify the added compute. Competitive and Strategic Implications The launch of Agentic Search underscores a broader shift in the AI industry toward agentic retrieval , where models are given toolkits and autonomy to orchestrate their own information‑gathering processes. By releasing a production‑ready framework and integrating it into its flagship products, Mistral is positioning itself as a serious contender in enterprise AI, not only on the strength of its base models but also through specialized infrastructure for knowledge‑intensive workloads. For enterprises, the technology offers a path to move beyond proof‑of‑concept chatbots and into applications where AI systems must routinely answer difficult, regulated or high‑stakes questions. If the reported benchmark gains generalize in real deployments, Agentic Search could enable more reliable AI copilots for finance, legal, compliance and operations teams, while also easing concerns about hallucinations and incomplete retrieval. As organizations continue to evaluate vendors on both model quality and retrieval performance, Mistral’s agentic layer may become a key differentiator – especially for customers who want the option to run search pipelines on‑premises while still tapping into state‑of‑the‑art agent capabilities.

Nic Reeve·
Unsealed Docs Show Microsoft Warned AInews Could Trigger a Doom Loop for Journalism
AI & Tech

Unsealed Docs Show Microsoft Warned AInews Could Trigger a Doom Loop for Journalism

On September 17, 2026, newly unsealed court filings in The New York Times’ copyright lawsuit against OpenAI and Microsoft showed senior Microsoft executives warning that their AInews products risk creating a “doom loop” that drains traffic and money from news outlets while degrading the quality of information on the web itself. What did the unsealed Microsoft documents say about AI and journalism? The unsealed Microsoft documents describe internal warnings that AI answer engines trained on news articles could both undermine publishers’ business models and weaken the online information ecosystem that those same AI systems depend on. Key passages from the filings show that Microsoft’s own researchers and product leaders were alarmed by how generative AI systems use and replace journalism: According to TechCrunch, an internal presentation written by Microsoft Director of Applied Science Brent Hecht in January 2024 described the impact of large-scale AI scraping and answer engines as a “doom loop” that would “hurt the performance of our models and the entire web at the same time.” The Washington Examiner reports that Hecht wrote, “Our AI content strategy has started a ‘doom loop’ that will hurt the performance of our models and the entire web at the same time,” calling the situation “highly unusual” because the end product threatens “the economic foundations of its essential suppliers.” Law360 and MLex note that internal documents quote Microsoft and OpenAI employees acknowledging that unlicensed use of millions of news articles could begin a doom loop that endangers their “content supply chain.” The Wrap cites filings where a Microsoft document warns that the companies’ AI approach had started a doom loop that would damage both model performance and “the entire web.” These statements appear in an unredacted memorandum filed by lawyers for The New York Times in its ongoing copyright case against OpenAI and Microsoft in federal court in Manhattan. The case has been moving through the courts since 2023. Who inside Microsoft raised alarms about AI scraping and labor “theft”? Concerns inside Microsoft were led by Brent Hecht, the company’s Director of Applied Science, who repeatedly warned that scraping journalism at scale for AI training amounted to unprecedented theft of human labor. The unsealed filings attribute several striking internal comments to Hecht: TechCrunch reports that Hecht described large-scale AI scraping of online content as “the largest theft of labor in human history” during internal discussions documented in January 2023 and January 2024. The New York Daily News notes that a senior Microsoft executive believed AI systems built on other people’s work would be seen as “an astonishing theft of unprecedented proportions” and possibly “the greatest robbery of labor in human history,” according to the unredacted court documents. BrandiconImage and The Wrap both quote Hecht calling the copying of news articles “an astonishing theft of unprecedented proportions” and potentially the “largest theft of labor in human history.” TweakTown, summarizing the filings, says Hecht argued that relying on “fair use” to justify mass scraping of news articles made a “complete mockery” of fair use as a legal concept. These warnings portray internal recognition that the AI training pipelines built on publishers’ work were not just legally risky. They were seen by some of the engineers and scientists responsible for the systems as ethically and economically corrosive for the entire news ecosystem. How is Microsoft’s AI answer engine affecting traffic to news publishers? The filings assert that Microsoft’s AI-powered answer tools dramatically cut referral traffic to news outlets, raising fears that this substitution effect could erode the financial base that supports professional journalism. Multiple sources describe internal metrics and testimony about how AI answers change user behavior: TechBeat reports that unredacted documents say Hecht warned in January 2024 that Microsoft’s Copilot answer engine reduced click-through rates to New York Times articles by up to 93% compared with traditional Bing search results. TweakTown’s summary of the same filings notes internal estimates that AI chatbots and answer boxes could cut publisher traffic by 51% to 94%, depending on the scenario and query type. The Wrap recounts Microsoft CEO Satya Nadella’s testimony that conversations with chatbots had already substituted for visits to news websites by “giving you the information right there on the website on the AI platform versus needing to go to the underlying source.” These numbers, all attributed to internal assessments and court testimony in 2024 and 2025, suggest that AI answer engines do not simply coexist with news sites. They can replace the need for many users to click through, weakening advertising revenue and subscriptions that depend on direct visits. What exactly is the “doom loop” Microsoft executives described? The “doom loop” described in the court filings refers to a self-reinforcing cycle in which AI systems undermine the economic viability of news outlets, leading to worse content on the web, which then harms the AI models that rely on that content. Internal documents quoted across several reports outline the logic of this loop: Ground News and EuropeSays explain that Hecht’s memo warned generative AI products had created a doom loop that is “eating the web and destroying the businesses that these companies stole from,” by substituting AI answers for visits to publishers. The Washington Examiner cites a Microsoft document saying, “It is highly unusual that an end-product threatens the economic foundations of its essential suppliers, but that is the situation we have created for our LLM business with respect to its ‘content supply chain.’” BrandiconImage notes that the filings describe a scenario in which declining traffic to news sites weakens the broader online ecosystem and ultimately reduces the quality of information available to AI systems. TweakTown’s coverage summarizes the loop as: AI answer engines cut traffic, lower financial incentives for journalists, shrink the supply of high-quality reporting, and then damage the very models that need that reporting for training. The core idea is simple. Less money for journalism means fewer reporters and less reliable news. AI models trained on that degraded content will perform worse, which harms users and the platforms themselves. How does the New York Times lawsuit frame these internal admissions? The New York Times uses the internal Microsoft and OpenAI admissions to argue that the companies knowingly built profitable AI systems on unlicensed news content, while recognizing that this strategy threatened the very publishers who produced that content. Recent coverage of the unsealed filings outlines the Times’ legal narrative: KuCoin’s legal news summary states that the newly unsealed memorandum in The New York Times v. OpenAI copyright lawsuit was written by Times lawyers and “largely comprised” statements and interviews with tech executives acknowledging that large language models were “built on content described by Microsoft executives as an unprecedented scale of theft.” Ground News reports that the filings present executives’ own words to show that large language models are “predatory” technologies, trained on “stolen content” that pose an “existential risk” to human writers, artists and media companies. MLex describes the new documents as showing knowledge of “AI copying costs to US news companies,” including recognition that unlicensed use of millions of articles to train chatbots could initiate the doom loop and represent the “largest theft of labor in human history.” Law360 notes that Microsoft and OpenAI employees had internally acknowledged for years that tools trained on news articles would likely replace publishers, leading to the doom loop scenario. By highlighting these internal statements, the Times aims to strengthen its claim that OpenAI and Microsoft knowingly relied on unlicensed journalism while foreseeing the damage to publishers. What are OpenAI’s internal concerns about publishers and substitution? The unsealed filings do not focus only on Microsoft. They also reveal internal OpenAI fears that chatbots would become direct substitutes for news publishers, undermining the business case for continued reporting. Several sources summarize these concerns: According to BrandiconImage, Nick Turley, who led the team developing ChatGPT, warned in a 2023 internal memo that AI represented an “existential threat” to publishers. The Wrap reports that Turley wrote that publishers faced an existential threat from AI products that were already “largely substitutive” and would become more so as the systems improved. Law360 states that OpenAI and Microsoft employees acknowledged for years that AI tools trained on news articles would likely replace publishers, contributing to the doom loop described in the filings. These internal comments echo the worries of many editors and reporters: if users can ask a chatbot for a summary instead of visiting a news site, long-term funding for independent journalism becomes precarious. What broader implications does this doom loop have for the future of news? The doom loop described by Microsoft and OpenAI staff suggests that current generative AI strategies could destabilize the business of news, reduce the quality of information online, and ultimately damage AI systems themselves unless new economic and legal arrangements emerge. Across the reports, several themes recur: Executives privately agree with publishers’ warnings that generative AI poses an “existential threat” to news organizations when it siphons both content and audience without paying for either. Internal Microsoft discussions emphasize that the economic foundations of journalism are part of the “content supply chain” for AI, meaning that harming publishers also harms AI products over time. The filings highlight the mismatch between short-term gains—offering instant answers that users love—and long-term risks, such as fewer reporters investigating public-interest stories because revenue has collapsed. Several analyses argue that the doom loop concept may push courts and regulators to consider new models, including licensing deals, compulsory fees, or explicit limits on scraping and training data drawn from professional news outlets. The immediate dispute centers on New York Times content and current AI products. The underlying question is whether the web that AI relies on can survive if its core economic engine—commercial and subscription-supported journalism—is hollowed out by the very systems that now scrape and summarize its work.

Nic Reeve·